
Since about 2020, AI has largely targeted on coaching greater and higher fashions. Massive language fashions (LLMs) ballooned from hundreds of thousands of parameters to trillions. This proved efficient: The biggest model of OpenAI’s GPT-3, launched in 2020, appropriately answered simply 43.9 p.c of questions on a well-liked knowledge-and-reasoning benchmark. Simply 4 years later, GPT-4o reached a rating of 88.7 p.c on the identical examination, successfully matching these of human specialists.
Superior AI labs are nonetheless coaching ever bigger fashions, however that coaching has considerably receded to the background of the AI dialog. In 2026, inference—using skilled fashions to provide code, write essays, or make photos of ourselves as elves—has come to the forefront.
“It’s like coaching is yesterday’s information,” says Matt Kimball, principal data-center analyst at Moor Insights & Technique. “All that any chief info officer needs to speak about is inference.” Nvidia CEO Jensen Huang, talking on the firm’s GTC 2026 convention, touted this alteration because the “inflection point of inference.”
A part of what’s prompted the shift could be very easy: LLMs have gotten helpful, so persons are utilizing them. On high of that, many fashions available on the market in the present day are reasoning fashions. In response to a consumer’s question, they run inference not simply as soon as however a number of occasions, reprompting themselves in a course of known as chain of thought. Reasoning fashions generate longer outputs, and fashions with excessive reasoning effort can produce as much as 20 times as a lot textual content as these with low or no effort. Including much more to the world’s inference workload, the rise of agentic AI has resulted in inference working not simply as a real-time response to a consumer’s question but in addition across the clock, working autonomously towards a user-defined aim.
Amazon’s Trainium chip was initially designed for AI coaching. Nevertheless, Amazon Net Providers selected to interrupt up AI inference into two components, with Trainium working the extra computationally complicated portion and Cerebras’s wafer-scale engine taking over the extra memory-intensive portion.Amazon
The ensuing explosion in inference demand has led to sudden alliances amongst tech giants. OpenAI and Amazon have deployed chips the dimensions of a dinner plate designed by Cerebras, regardless of Amazon having its personal Trainium chips. Nvidia bought key expertise and mental property from AI-inference startup Groq in a controversial deal value US $20 billion. And Anthropic is paying LLM competitor SpaceXAI over a billion {dollars} per 30 days to lease spare compute.
Though they may appear related, AI coaching and AI inference are computationally completely different. These massive strikes from tech giants sign that with a view to help the inference demand, we’re going to want a really completely different mixture of {hardware} than specialists might have anticipated even a few years in the past.
How does AI inference differ from AI coaching?
An untrained LLM is sort of a jumble of Scrabble tiles on a desk. As an alternative of single letters, although, the tiles present fragments of phrases, known as tokens. The whole lot you’d want to put in writing virtually something is current, however nothing is smart.
Coaching a mannequin organizes this jumble utilizing a guessing sport performed at scale. The mannequin is proven actual textual content with the subsequent token hidden and requested to foretell what comes subsequent. After every guess, the right token is revealed after which in comparison with the prediction, and the distinction is used to calculate the mannequin’s accuracy. The sport is performed not with a single sentence however over billions of passages.
Whereas an actual sport of Scrabble might be performed over a bag of chips and some drinks, AI coaching is computationally intense. The mannequin updates its parameters by backpropagation, a course of that repeatedly calculates how every of a mannequin’s billions or trillions of parameters ought to shift to make the subsequent prediction higher. For this reason tech giants are building bigger information facilities than ever earlier than.
Ultimately the mannequin’s creator decides additional coaching isn’t value the fee, and the guessing sport stops. Backpropagation ends, the parameters are frozen, and the LLM turns into a pretrained mannequin. High-quality-tuning—a brief coaching run on smaller, extra specialised information—provides closing tweaks, and the mannequin is deployed.

Nvidia’s Groq 3 language-processing unit minimizes information motion by putting on-chip SRAM reminiscence and computational blocks within the order they’re wanted on-chip.
Nvidia
Subsequent comes inference. That is the method of utilizing the deployed mannequin, which, now that it’s been skilled, has realized to spit out Scrabble tiles—tokens—in a wise order.
You may assume that AI inference is much less computationally demanding as a result of the backpropagation calculations used to replace parameters are eradicated. However Sudeep Bhoja, founder and CTO of the inference-hardware firm d-Matrix, explains that inference provides new challenges.
The fashions are “autoregressive” in nature. That’s, the subsequent output will depend on the earlier one. “So to generate the subsequent token, it’s important to learn the entire weights and the entire [context] from the earlier token,” explains Bhoja. The context contains your entire prompts, the entire LLM’s replies, and the entire recordsdata you add. It’s a number of information and a number of processing.
An LLM generates its reply in two phases: prefill and decode. Prefill is the mannequin studying a immediate. It processes each token directly, computing how every token pertains to all of the others. This operation known as attention, and it’s a defining attribute of the transformer structure behind fashionable LLMs. It permits them to reply to a phrase in its sentence, paragraph, and bigger context somewhat than by itself. Consider it like arranging Scrabble tiles earlier than you place them in a sport. Many gamers transfer tiles round to think about how they join. Self-attention performs an analogous function, although as a substitute of transferring bodily tiles, every token sends a question to the others and receives a rating indicating the token’s relevance.
These queries end in two varieties of vectors: the keys and values. They’re sometimes positioned in a retailer known as the KV cache. This isn’t strictly required, as a mannequin may as a substitute recompute these vectors with every new token it generates. However almost all LLMs use a KV cache to cut back how a lot computing they do. The KV cache is saved in reminiscence and turns into a scratchpad to which the LLM can return to know a dialog, and although it begins small, it will probably swell to dozens of gigabytes.
Prefill is an issue that may be simply divided up and labored on in parallel. For this reason GPUs turned the dominant AI accelerator as LLMs surged in reputation. Graphics rasterization (computing the colour of each pixel on a display) can be massively parallel, so GPU architectures had been a pure match.

Cerebras’s wafer-scale engine chips maximize reminiscence bandwidth by holding all the things—each reminiscence and computational models—facet by facet on the dinner-plate-size chips.
Cerebras
Subsequent comes decode. Right here, the mannequin generates its reply one token at a time. At every step it takes the newest token, weighs it in opposition to all the things within the KV cache, makes use of that info to foretell the subsequent token, and provides the brand new token’s key and worth to the cache. Then it repeats in sequence, token by token.
That is the place the autoregressive nature of the mannequin works in opposition to inference velocity. Predicting every token requires studying the complete mannequin from reminiscence, and that mannequin consists of presumably tens to lots of of gigabytes of parameters (the numbers representing what the mannequin realized in coaching). Crucially, that is along with the reminiscence required to retailer the KV cache.
Because of this, the motion of all this information by reminiscence usually requires extra bandwidth than inference {hardware} has obtainable. So no less than a number of the computing components of a GPU sit idle because it waits for information. Researchers found that Nvidia H100 GPUs working open-source LLMs sit idle 50 to 80 p.c of the time.
Reminiscence’s function in inferencing
Shahriar “Sha” Rabii, former head of silicon engineering at Meta and cofounder of the AI startup Majestic Labs, says idled processors are why many firms which are attempting to enhance AI-inference efficiency are laser-focused on reminiscence. “With the GPU-based strategy, you find yourself drastically over-provisioning compute and starved on reminiscence. That’s driving the large [memory] scale out,” he says.
Bhoja’s d-Matrix and Rabii’s Majestic Labs each concentrate on this reminiscence bottleneck. Nevertheless, their firms think about completely different options.
d-Matrix’s second-generation AI accelerator, Raptor, goals to enhance inference efficiency by minimizing the gap between compute and reminiscence. The GPUs in most present AI-inference deployments do that by putting high-bandwidth reminiscence (HBM) across the perimeter of the GPU. Every HBM is a stack of DRAM dies linked collectively and linked to a superfast interface to the GPU. That is nice for coaching, however for inference, the quantity of reminiscence you possibly can stack this fashion and the bandwidth it will probably present depart one thing to be desired.
d-Matrix’s Raptor removes that bottleneck by stacking an AI accelerator on a DRAM die. As an alternative of stacking reminiscence, d-Matrix stacks reminiscence and compute. Bhoja says this reduces the gap that information should journey to “micrometers as a substitute of millimeters.” Like constructing a skyscraper, going vertical makes it potential to do extra inside the identical bodily footprint.
Majestic takes the other strategy. As an alternative of attempting to reduce the size that information should journey between compute and reminiscence, the corporate is targeted on enhancing the reminiscence interface to accommodate longer wire traces whereas holding bandwidth excessive. Longer wires enable Majestic to attach reminiscence stacks that aren’t instantly subsequent to the GPU, eradicating the house limitation of HBM.
“A reminiscence interface has a really brief bodily distance it will probably function over. Within the case of HBM, it’s as much as 2 or 3 millimeters. You will have this shoreline across the periphery, which is the one place the place you possibly can put HBM,” says Rabii.
Majestic claims its reminiscence interface can transmit bits so far as a couple of meter. That’s achieved with a proprietary copper hyperlink and a memory-aggregator chip that coordinates information. “The aggregator is the endpoint for the high-speed interface and a option to fan out to many, many commodity DRAM chips,” says Rabii. Due to this, Majestic can help as much as 128 terabytes of DRAM reminiscence in a single server rack—a big enhance over Nvidia’s GB300 NVL72 rack, which has about 20 TB of HBM3E.
d-Matrix and Majestic have one factor in widespread: As an alternative of HBM, they each use off-the-shelf DRAM. That is the commonest kind of laptop reminiscence on the earth; it’s in all the things from smartphones to automobiles. Reminiscence analyst Jim Handy says HBM prices two to 3 occasions as a lot as DRAM. d-Matrix and Majestic selected DRAM partly due to this worth benefit. Nevertheless, the proponents of HBM, which embody reminiscence giants like Samsung and SK Hynix, aren’t sitting idle.
HBM4, the most recent model of HBM reminiscence, is now in manufacturing and might be utilized by Nvidia’s Vera Rubin GPU, which is predicted to ship within the second half of 2026. Hoshik Kim, head of memory-systems analysis at SK Hynix, says HBM4 “will decisively break the reminiscence bottlenecks constraining AI inference in the present day” by doubling HBM’s most reminiscence bandwidth and growing the quantity of HBM reminiscence per stack.
Combining chips for sooner inference
The large gamers—Nvidia and Amazon—are going for an all-chips-on-deck strategy. Nvidia’s GPUs and Amazon’s Trainium coaching accelerators are nonetheless nice for a part of the inference workload: the prefill stage, the place all of the context keys and values are calculated. However to speed up decode, the half the place new tokens are generated, they want to new, memory-centric architectures from smaller gamers.
In Nvidia’s case, the smaller participant was Groq (to not be confused with Grok, the household of LLMs skilled by SpaceXAI). Nvidia bought mental property and employed expertise from Groq on the finish of 2025, and simply three months later on the Nvidia’s GTC 2026 convention, Jensen Huang unveiled the Nvidia Groq 3 language-processing unit (LPU). Groq’s structure depends on reminiscence—in its case, SRAM—constructed instantly into the chip’s structure.
Except you’re a chip architect, or a hardcore PC gamer, you most likely by no means give SRAM a thought. SRAM has the advantage of being tightly built-in right into a compute chip’s structure—it’s on the identical piece of silicon because the processor—and has the disadvantage of being much less dense and dearer than DRAM. Most chips embody only some dozen megabytes of SRAM. AI inference, nevertheless, has ignited new curiosity in SRAM as a method of bringing the mannequin weights saved in reminiscence nearer to compute.
Ian Buck, vice-president and common supervisor of hyperscale and high-performance computing at Nvidia, says the LPU has a a lot completely different set of priorities than the corporate’s GPUs. The LPU has far much less uncooked computing energy than a normal GPU, but it surely beneficial properties 500 megabytes of on-die SRAM linked on to its floating-point math models. “The profit is the reminiscence bandwidth. The LPU has seven occasions the reminiscence bandwidth of the GPU,” he says.
Between the Rubin GPU and the Groq LPU, prefill and decode can each be accelerated to get the very best of each worlds, the idea goes. “We do all the eye math and context processing on the Vera Rubin [GPU] rack,” explains Buck. “For all of the knowledgeable calculations…the matrix multiplications, we try this half on the LPU.” The corporate packs 256 LPUs into the Groq 3 LPX, a system the dimensions of a data-center rack.
Amazon Net Providers (AWS), for its half, struck a deal with Cerebras, to pair the Trainium accelerator with Cerebras’s Wafer-Scale Engine 3 (WSE-3). Cerebras takes an analogous strategy to Groq, although at a a lot bigger scale. WSE-3 turns a whole silicon wafer right into a single chip that incorporates over 4 trillion transistors. The design doesn’t hook up with exterior reminiscence however as a substitute etches 44 gigabytes of SRAM into every wafer. “We retailer the [model] weights on the SRAM,” says James Wang, previously director of product advertising and marketing at Cerebras who has since moved to SpaceXAI. “In order that’s simply 40 to as much as 80 billion parameters that we will help on one chip.”
Amazon plans to make use of AWS Trainium chips for prefill, and Cerebras for decode. However Cerebras’s chips may go it alone in inference. WSE-3 was deployed by OpenAI to power GPT-5.3-Codex-Spark, a variant of the corporate’s coding mode, outputting over 1,000 tokens per second. For comparability, OpenAI’s customary GPT-5.4 deployment outputs 50 to 125 tokens per second.
Cerebras may deal with prefill with out transferring the workload to completely different specialised chips. For this, it networks collectively a number of WSE-3 chips to kind a single pool of reminiscence. “Commercially, we’ve carried out about 500 billion parameters for our clients up so far,” says Wang. “However the structure has no innate limitation when it comes to what number of parameters it should do.”
Regardless of these variations in technique, Nvidia and AWS appear to agree that the way forward for AI inference might be solved by a methods strategy that swimming pools completely different sorts of chips collectively to deal with the most important LLMs. Or, as Buck says: “To do fashionable AI inference, you want all of the chips.”
Studying to do extra with much less (bits)
Nvidia turned the world’s most dear tech firm as a result of it designed the world’s most desired GPUs. However not the entire consideration is targeted on enhancing AI-inference {hardware}. AI researchers are additionally studying tips on how to optimize LLM software program and {hardware} in tandem to make the very best use of the reminiscence and compute elements.
Most computer systems retailer numbers in a 32-bit or 64-bit format. These decide what number of bits can be found to signify a single quantity. If too few bits can be found, the quantity can’t be saved with out dropping info. The standard of an LLM advantages from more-precise quantity codecs, however this creates an issue for inference efficiency. Extra-precise numbers aren’t free. The bits that describe them take up more room in reminiscence and require extra silicon and vitality to compute.
Gilles Backhus, cofounder of the AI-accelerator firm Tensordyne, says this creates a pressure between mannequin dimension and quantity precision. “Would you like a mannequin that’s dimension x however runs in 8-bit, or would you like a mannequin that’s twice the dimensions however runs in 4-bit?” The dimensions of every mannequin might be roughly the identical when it comes to reminiscence and compute, “however the 4-bit strategy provides you twice as many synapses, if you’ll. And persons are determining that [the 4-bit approach] is value it.”
The method of changing an LLM from a more-precise quantity format to a less-precise format known as quantization, and it’s been in use for a number of years. Nevertheless, researchers are discovering new methods to quantize fashions down whereas retaining a big majority of the mannequin’s high quality.
Nvidia just lately created a brand new 4-bit quantity format, NVFP4, for this objective. AMD, Intel, and Qualcomm have as a substitute rallied round a competing 4-bit quantity format known as MXFP4 that Nvidia additionally contributed to growing. “It’s the black artwork of AI,” says Buck, of Nvidia. When Nvidia quantized DeepSeek-R1 from FP8 to NVFP4, scores on seven main benchmarks degraded by lower than one p.c whereas performance improved by three times, the corporate says.
Quantization is probably going simply the tip of the spear, as AI researchers and startups are investigating a range of alternatives for optimization, a few of which may dramatically change the silicon present in AI-inference {hardware}.
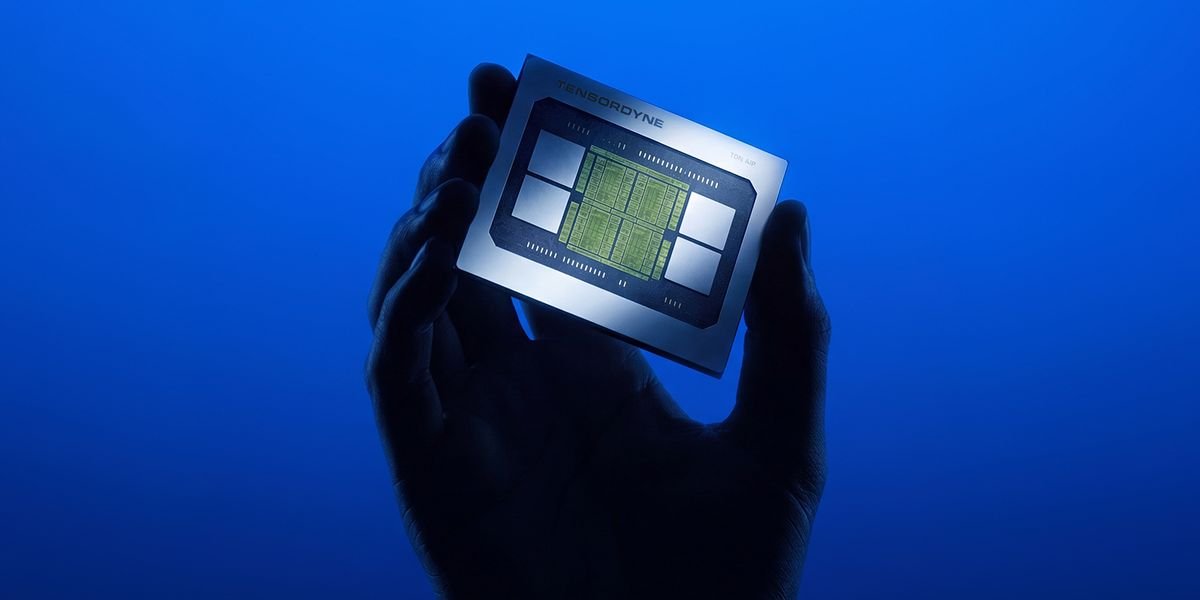
 Tensordyne’s distinctive strategy to AI inference combines a logarithmic quantity format with bespoke {hardware} within the firm’s Napier chip. Tensordyne
Tensordyne is predicted to accelerate AI inference with a logarithmic quantity system that leans on a property of logarithms: The log of A occasions B equals the log of A plus the log of B. So, storing numbers as their exponents lets the chip add the place it could in any other case multiply. That issues in silicon as a result of multiplier circuits draw extra energy and use extra die space than adders do. Tensordyne says its rack-scale {hardware}, known as Napier, can produce as much as 1,300 tokens per second per consumer, and may achieve this whereas utilizing lower than a tenth as a lot energy as comparable Nvidia {hardware}.
Etched, a startup primarily based in San Jose, Calif., is even designing AI accelerators that translate the transformer structure utilized by LLMs instantly into silicon. Moderately than constructing general-purpose GPUs, the corporate is wiring up the connections wanted for environment friendly transformer calculations into its chip, making the chip a lot much less versatile however extra environment friendly for the duties most carried out by present LLMs. The corporate says its first AI accelerator, Sohu, can run Meta’s Llama 70B mannequin at a surprising 500,000 tokens per second, although this strategy additionally means it gained’t be capable of run LLMs that transfer away from a typical transformer structure.
Whether or not these concepts will show fruitful stays to be seen. Etched simply shipped their first rack in August. Tensordyne believes its first {hardware} might be obtainable in 2027. Even so, these startups present how the demand for inference efficiency is fueling unconventional concepts.
Inference is everybody’s sport
The sheer number of approaches to AI-inference acceleration—stacking compute on reminiscence, extending interfaces from millimeters to meters, utilizing a whole silicon wafer for SRAM, squeezing fashions into 4 bits—raises a query: Which goes to win, and which goes to lose?
However that’s doubtless not the precise query, specialists say. The demand for AI is at the moment insatiable, and whereas fears of an AI bubble stalk the trade, it has but to hamper progress.
Quite the opposite, Kimball of Moor Insights & Technique thinks inference may drive intense demand for AI {hardware} in the long run, as a result of it’s not apparent the place that demand will finish. “You would add one million brokers into your group,” he says. “These items work 24 hours a day; they don’t go residence at 5 at evening like we do.”
If AI inference stays as fascinating as Kimball expects, the evolution is prone to comply with the identical trajectory because the CPU. The CPU didn’t enhance alongside a single axis however as a substitute throughout multiple fronts concurrently. As soon as transistor scaling slowed, chip and system structure improvements of all types proliferated. The listing of particular person improvements that led to in the present day’s ubiquitous, highly effective private compute may fill dozens of books.
Just a few many years from now, the historical past of AI inference innovation will present related depth.
From Your Web site Articles
Associated Articles Across the Net
